VFMUL
Operation
Multiplies corresponding active floating-point elements.
Assembler Syntax
VFMUL.{H|S|D}(x) Pn(p), Vn(v), Vn(w)
VFMUL.{H|S|D}(x) Pn(p), <ea>(e), Vn(v)
VFMUL.{H|S|D}(x) Pn(p), Vn(v), <ea>(e)
Privilege
Unprivileged
Required CPUID flags
FP
VECTOR
VECTORFP
VFMUL multiplies each active destination element by its corresponding source element. For H, S, and D elements, the exact product is rounded according to the floating-point environment. The register form and the memory-source form write the result to the destination vector lane. An inactive destination lane retains its previous value.
The memory-destination form reads each active destination element, multiplies it by the corresponding source-register element, and writes the result back to that memory element. Inactive memory elements retain their previous values, making the destination transaction a lane-wise read-modify-write.
2.75in
Encodings
VFMUL.{H|S|D}(x) Pn(p), Vn(v), Vn(w)
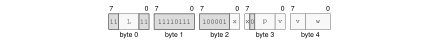
Format: Instruction format for VFMUL.{H|S|D}(x) Pn(p), Vn(v), Vn(w)
size — allowed: 0x5..0x7 [reserved_vector_element_type]
2.75in VFMUL.{H|S|D}(x) Pn(p), <ea>(e), Vn(v)
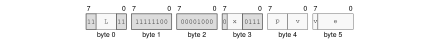
Format: Instruction format for VFMUL.{H|S|D}(x) Pn(p), <ea>(e), Vn(v)
size — allowed: 0x5..0x7 [reserved_vector_element_type]
2.75in VFMUL.{H|S|D}(x) Pn(p), Vn(v), <ea>(e)
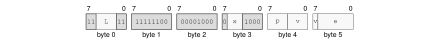
Format: Instruction format for VFMUL.{H|S|D}(x) Pn(p), Vn(v), <ea>(e)
size — allowed: 0x5..0x7 [reserved_vector_element_type]
dst — excluded: immediate [invalid_destination]