VREDXOR
Operation
Reduces selected integer lanes with bitwise XOR and writes the scalar result to Rn.
Assembler Syntax
VREDXOR.{B|W|L|Q}(z) Pn(p), Vn(v), Rn(r)
VREDXOR.{B|W|L|Q}(z) Pn(p), <ea>(e), Rn(r)
Privilege
Unprivileged
Required CPUID flags
VECTOR
The governing predicate chooses which source elements participate. The Vn form reads those elements from the vector source. The VEA form first reads a complete vector-length source from memory and applies the same predicate selection.
Selected elements are combined with bitwise XOR at the B, W, L, or Q element width. The selected-width result bit pattern occupies the low bits of Rn, and all higher bits are zero. If the predicate selects no elements, Rn receives zero.
2.75in
Encodings
VREDXOR.{B|W|L|Q}(z) Pn(p), Vn(v), Rn(r)
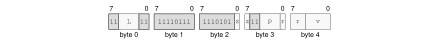
Format: Instruction format for VREDXOR.{B|W|L|Q}(z) Pn(p), Vn(v), Rn(r)
2.75in VREDXOR.{B|W|L|Q}(z) Pn(p), <ea>(e), Rn(r)
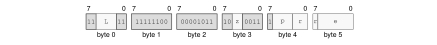
Format: Instruction format for VREDXOR.{B|W|L|Q}(z) Pn(p), <ea>(e), Rn(r)